How to Build a Multi-Modal RAG Pipeline for Images and Documents in Python
In this article, you will learn how to build a multi-modal RAG pipeline in Python that retrieves and reasons over both text and images extracted from complex documents.
Topics we will cover include:
- How to parse a PDF into separate text and image elements using the unstructured library.
- How to generate searchable text summaries for extracted images using GPT-4o, and store everything in a multi-vector retrieval system.
- How to query the pipeline with a multimodal prompt that passes both text chunks and raw images to GPT-4o for a grounded final answer.
Standard retrieval-augmented generation works great for plain text. But feed it a PDF packed with embedded charts, scanned diagrams, or data tables, and things fall apart fast.
Text-based chunking destroys table formatting and skips images, so your pipeline ends up answering questions from an incomplete picture of the document.
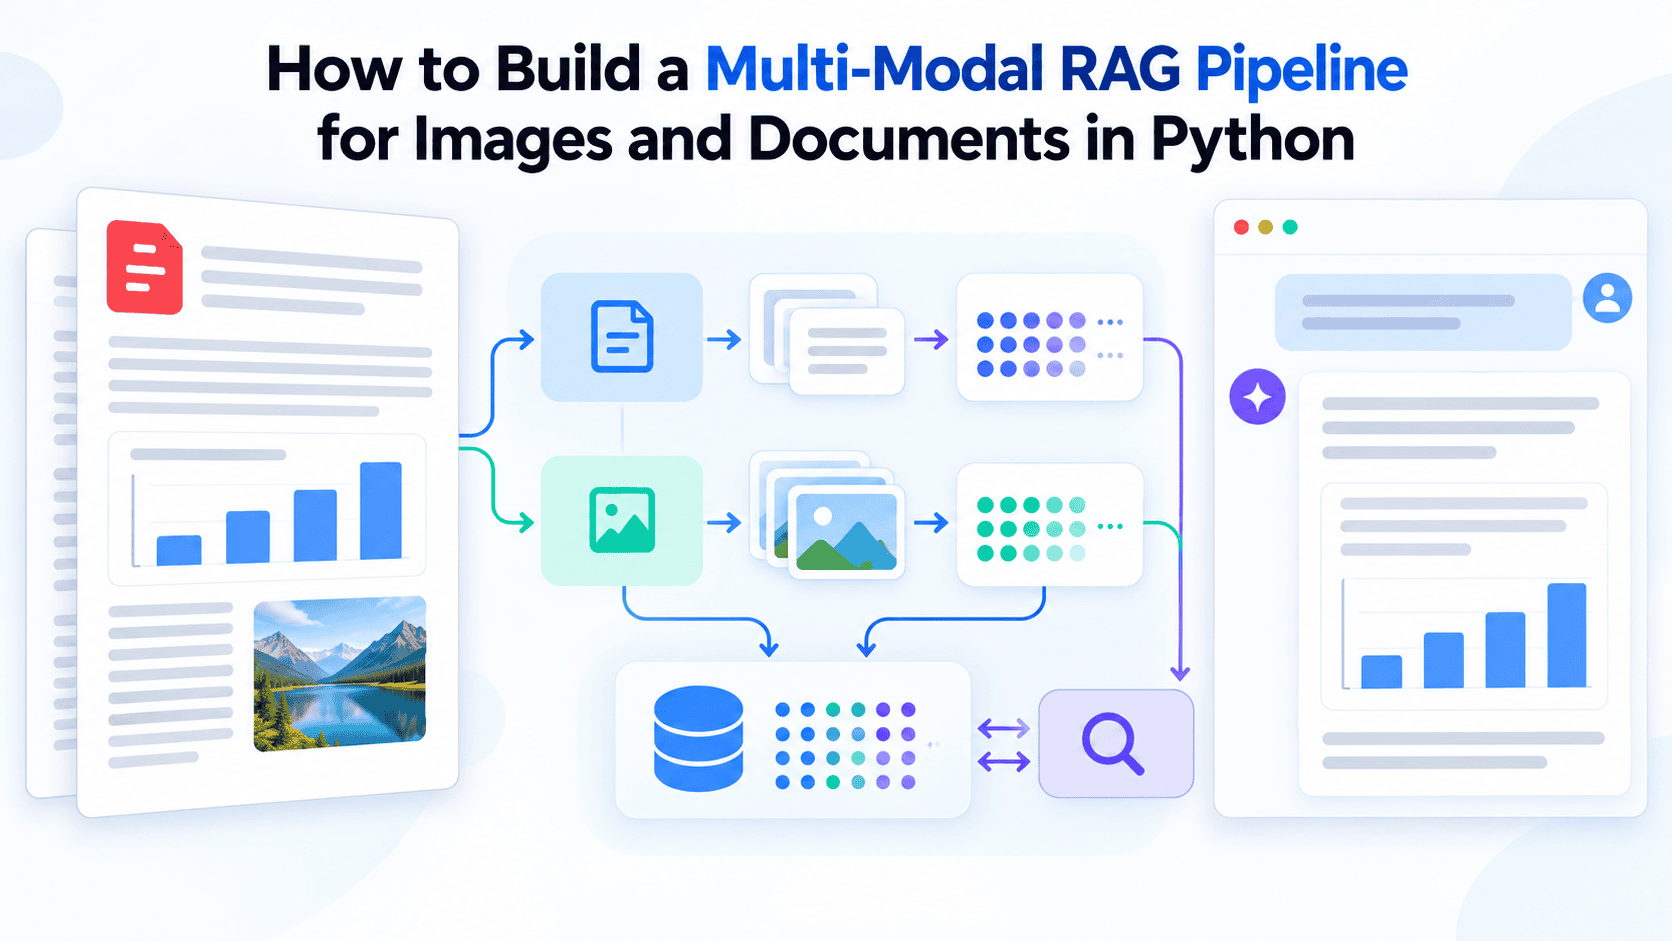
A multi-modal RAG pipeline fixes this by treating images as first-class retrievable objects alongside text. In this tutorial, we’ll build one in Python using LangChain, the unstructured library, and the OpenAI API.
We’ll parse a complex PDF into separate text and image elements, generate searchable summaries for each image, store everything in a multi-vector retrieval system, and query it with a prompt that returns both text and visual evidence to GPT-4o for a final answer.
As covered in The Multimodal AI Guide on KDnuggets, modern AI systems are designed to reason across content types natively. This tutorial applies that principle to a practical problem: documents that mix prose, tables, and embedded images.
Where the MLM multi-modal RAG implementation takes a local PyTorch approach suited to audio and image-heavy workloads, this guide uses an API-driven architecture that runs on standard hardware and fits business document use cases well.
Prerequisites and Setup
You’ll need an OpenAI API key and the following packages installed. The poppler-utils system dependency is required by unstructured to extract images from PDFs.
pip install langchain langchain-openai unstructured[pdf] chromadb pillow
apt-get install -y poppler-utils
Set your API key as an environment variable before running any code:
import os
os.environ["OPENAI_API_KEY"] = "your-api-key-here"
The pipeline has four stages: parse, summarize, store, and retrieve. Each one maps to one of the code blocks below.
Step 1: Parsing the Document into Text and Image Elements
The unstructured library does the heavy lifting here. Its partition_pdf() function reads the document and classifies each element by type. It separates paragraphs, tables, and embedded images instead of treating the whole file as a flat stream of characters.
from unstructured.partition.pdf import partition_pdf
raw_elements = partition_pdf(
    filename="report.pdf",
    extract_image_block_types=["Image"],
    extract_image_block_output_dir="./extracted_images",
    infer_table_structure=True,
    chunking_strategy="by_title",
    max_characters=4000,
)
extract_image_block_output_dir tells unstructured where to save extracted image files, while extract_image_block_types controls which element types get pulled out.
Next, separate the returned elements into text and image lists:
text_elements = []
image_paths = []
for el in raw_elements:
    if "CompositeElement" in str(type(el)):
        text_elements.append(str(el))
    elif "Image" in str(type(el)):
        image_paths.append(el.metadata.image_path)
print(f"Extracted {len(text_elements)} text chunks, {len(image_paths)} images")
The loop separates composite text chunks from image elements, storing the image file paths for the next step.
Step 2: Generating Searchable Summaries for Each Image
Text-based vector databases can’t index raw images, so each image needs a text representation that captures its content in a way that’s retrievable by a natural language query. This step passes every extracted image to GPT-4o with a prompt designed to produce dense, searchable descriptions.
import base64
from openai import OpenAI
client = OpenAI()
With the client ready, define a function that base64-encodes each image and sends it to GPT-4o with a retrieval-focused prompt:
def summarize_image(image_path):
    with open(image_path, "rb") as f:
        image_data = base64.b64encode(f.read()).decode("utf-8")
    response = client.chat.completions.create(
        model="gpt-4o",
        messages=[{"role": "user", "content": [
            {"type": "image_url", "image_url": {"url": f"data:image/png;base64,{image_data}"}},
            {"type": "text", "text": "Describe this image in detail for use in a search system."}
        ]}]
    )
    return response.choices[0].message.content
To run it across all extracted images:
image_summaries = [summarize_image(p) for p in image_paths]
Each summary becomes the searchable proxy for its source image. The raw image file is kept separately and retrieved by reference when a query matches its summary.
A note on costs: every extracted image triggers a GPT-4o API call at indexing time. If you’re working with large documents full of embedded logos or icons, consider filtering out images below a minimum file size before passing them to summarize_image().
Step 3: Building the Multi-Vector Store
This is where the architecture diverges from standard RAG. A MultiVectorRetriever maintains two stores: a vector store that holds embedded text chunks and image summaries for similarity search, and a document store that holds the raw source content linked to those embeddings through unique IDs.
import uuid
from langchain_openai import OpenAIEmbeddings
from langchain_chroma import Chroma
from langchain.storage import InMemoryStore
from langchain.retrievers.multi_vector import MultiVectorRetriever
from langchain_core.documents import Document
embeddings = OpenAIEmbeddings(model="text-embedding-3-small")
vectorstore = Chroma(embedding_function=embeddings)
docstore = InMemoryStore()
retriever = MultiVectorRetriever(vectorstore=vectorstore, docstore=docstore)
text_ids = [str(uuid.uuid4()) for _ in text_elements]
image_ids = [str(uuid.uuid4()) for _ in image_summaries]
This initializes both stores and generates a unique ID for each element. The vector store holds the searchable summaries; the document store holds the raw content.
With the IDs in place, populate both:
retriever.vectorstore.add_documents(
    [Document(page_content=t, metadata={"doc_id": i}) for t, i in zip(text_elements + image_summaries, text_ids + image_ids)]
)
raw_docs = (
    [Document(page_content=t, metadata={"type": "text"}) for t in text_elements] +
    [Document(page_content=p, metadata={"type": "image"}) for p in image_paths]
)
retriever.docstore.mset(list(zip(text_ids + image_ids, raw_docs)))
Wrapping raw content in Document objects with an explicit type field keeps the retrieval logic in Step 4 clean. Each ID links an embedded summary in the vector store to its corresponding raw Document in the document store.
Step 4: Querying the Pipeline with Multimodal Retrieval
At query time, the retriever embeds the question and finds the closest matches across both text and image summaries. If a match points to an image path, the raw file is loaded and passed to GPT-4o alongside any retrieved text. GPT-4o then generates an answer grounded in both content types.
def query_pipeline(question):
    docs = retriever.invoke(question)
    text_content, image_content = [], []
    for doc in docs:
        if doc.metadata.get("type") == "image":
            with open(doc.page_content, "rb") as f:
                img_b64 = base64.b64encode(f.read()).decode("utf-8")
            image_content.append({"type": "image_url", "image_url": {"url": f"data:image/png;base64,{img_b64}"}})
        else:
            text_content.append({"type": "text", "text": doc.page_content})
The metadata check routes each retrieved Document cleanly: image paths get opened and base64-encoded, while text chunks pass through as-is.
The function then assembles both into a single multimodal GPT-4o call:
response = client.chat.completions.create(
    model="gpt-4o",
    messages=[{"role": "user", "content": text_content + image_content + [{"type": "text", "text": question}]}]
)
return response.choices[0].message.content
Call the function with any question about the document:
answer = query_pipeline("What does the revenue chart show for Q3?")
print(answer)
GPT-4o reasons across all retrieved evidence - both text and images - before returning a final answer.
Conclusion
This pipeline handles what standard RAG can’t: documents where the most important information lives in charts, diagrams, or embedded graphics. The four stages are: parse with unstructured, summarize images with GPT-4o, store with a multi-vector retriever, and query with a multimodal prompt.
This pattern scales to research papers, financial reports, product manuals, and any document type that mixes text with visuals.
From here, you can extend the pipeline by adding re-ranking to improve retrieval precision, persisting the Chroma vector store to disk for production use, or exploring vision-language models like ColPali that skip the parsing step by embedding document pages as images.
Clear walkthrough - the part I keep wrestling with in practice is keeping the image and text embeddings in the same retrieval space so the fusion step doesn’t silently bias toward whichever modality has more tokens. Curious whether you’ve seen better recall by re-ranking with a cross-modal scorer instead of concatenating early. Would love a follow-up on incremental indexing when the document set changes daily.
Hi Codex…You raise some excellent points, particularly regarding the potential bias introduced when combining image and text embeddings. Simply concatenating representations doesn’t necessarily preserve the relative importance of each modality, especially when the amount of textual information significantly exceeds the visual content.
I would lean toward retrieving candidates from each modality separately, using something like reciprocal rank fusion to combine the results, and then applying a cross-modal reranker. This provides more control over how each modality contributes to the final ranking.
One important distinction is that reranking can improve the relevance of the top results, but it cannot recover relevant images or documents that were missed during the initial retrieval. Evaluating recall at different retrieval depths would therefore be important.
Incremental indexing is another excellent topic for a follow-up. In a production environment where documents change daily, rebuilding the entire embedding index is neither efficient nor particularly practical. Tracking document identifiers, timestamps, and content hashes would allow us to identify changes and update only the affected embeddings while removing obsolete entries.
I think a useful follow-up would be to compare early fusion against late fusion with cross-modal reranking, using retrieval recall, ranking quality, and computational cost as evaluation metrics. Adding incremental indexing to that comparison would bring the discussion much closer to the challenges encountered when deploying multimodal RAG systems in practice.
Comments
No comments yet. Start the discussion.